Loading...
YOU ARE
NOW
ENTERING GROWX CRAWL
NOW
ENTERING GROWX CRAWL
SCROLL
TO
CASE STUDY
TO
CASE STUDY
AI-NATIVE
PRODUCT STUDIO &
INTERNAL R&D
PRODUCT STUDIO &
INTERNAL R&D
© 2026 // GL-X
ALL RIGHTS RESERVED
ALL RIGHTS RESERVED
GrowXCrawl
[ GROWXLABS ]
YOU ARE
NOW
ENTERING GROWX CRAWL
NOW
ENTERING GROWX CRAWL
SCROLL
TO
CASE STUDY
TO
CASE STUDY
AI-NATIVE
PRODUCT STUDIO &
INTERNAL R&D
PRODUCT STUDIO &
INTERNAL R&D
© 2026 // GL-X
ALL RIGHTS RESERVED
ALL RIGHTS RESERVED
GrowXCrawl
// INTERNAL R&D
Production-grade web crawling API for scraping pages, extracting structured data, crawling websites, processing URLs in batches, capturing screenshots, generating PDFs, and auditing SEO.
PROJECTWeb Research
BUILT BYGrowxLabs
RUNTIMELocal-first
// 01 OVERVIEW
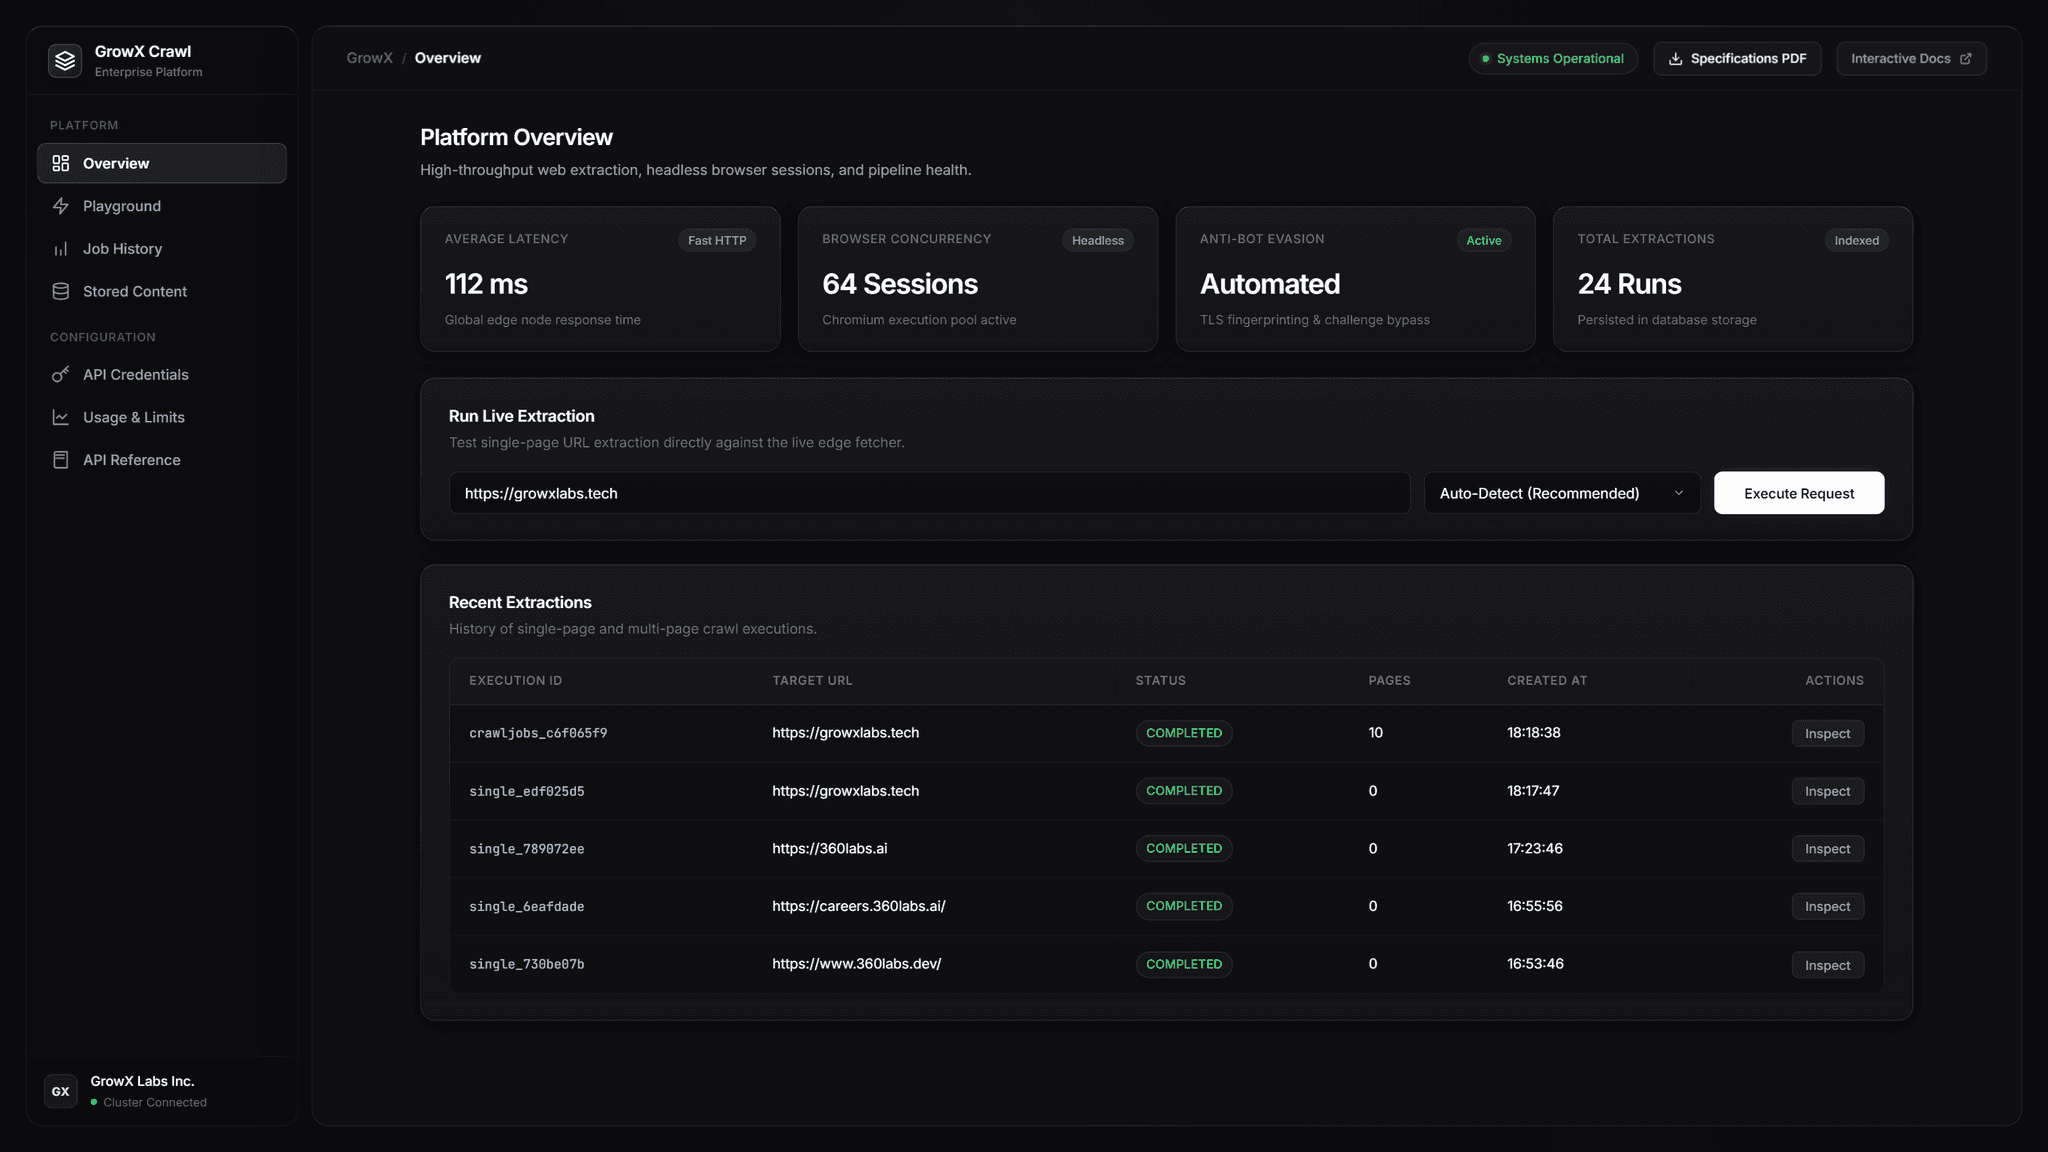
One API, seven capabilities. GrowX Crawl scrapes individual pages using fast HTTP, a browser, or stealth fetching when needed, and extracts specific data with CSS or XPath selectors. It can crawl up to 50 pages across five levels or process batches of up to 100 URLs, with job tracking and webhooks for longer runs. It also captures screenshots, generates PDFs, and audits site SEO. Proxy support, robots.txt controls, and response caching are built in.
// 02 SPECIFICATIONS
SpecificationGrowX Crawl
Capabilities7: scrape, extract, crawl, batch, screenshot, PDF, URL-based SEO audit
Fetching3 modes: Fast HTTP, headless browser, stealth
Crawl limitUp to 50 pages and five levels deep
Batch limitUp to 100 URLs per job; configurable concurrency
Job deliveryStatus polling and optional completion webhook
FormatsPNG/JPEG screenshots and A4, Letter, or Legal PDFs
// 03 FEATURES
01
Fetches standard and JavaScript-heavy pages, switching methods when a page resists extraction
02
Pulls the exact fields you need with CSS or XPath rules
03
Follows links through a site, up to 50 pages and five levels
04
Processes URL lists in batches of up to 100
05
Creates page screenshots and PDFs, and checks a URL’s SEO
06
Provides API key access, usage limits, job tracking, webhooks, and scrape caching
// 04 ARCHITECTURE
// AI UTILITYExplore this project with AI
/
Interested
in GrowX Crawl?
Let's discuss how this can work for you.
Get in Touch// END OF CASE STUDYGROWX CRAWL